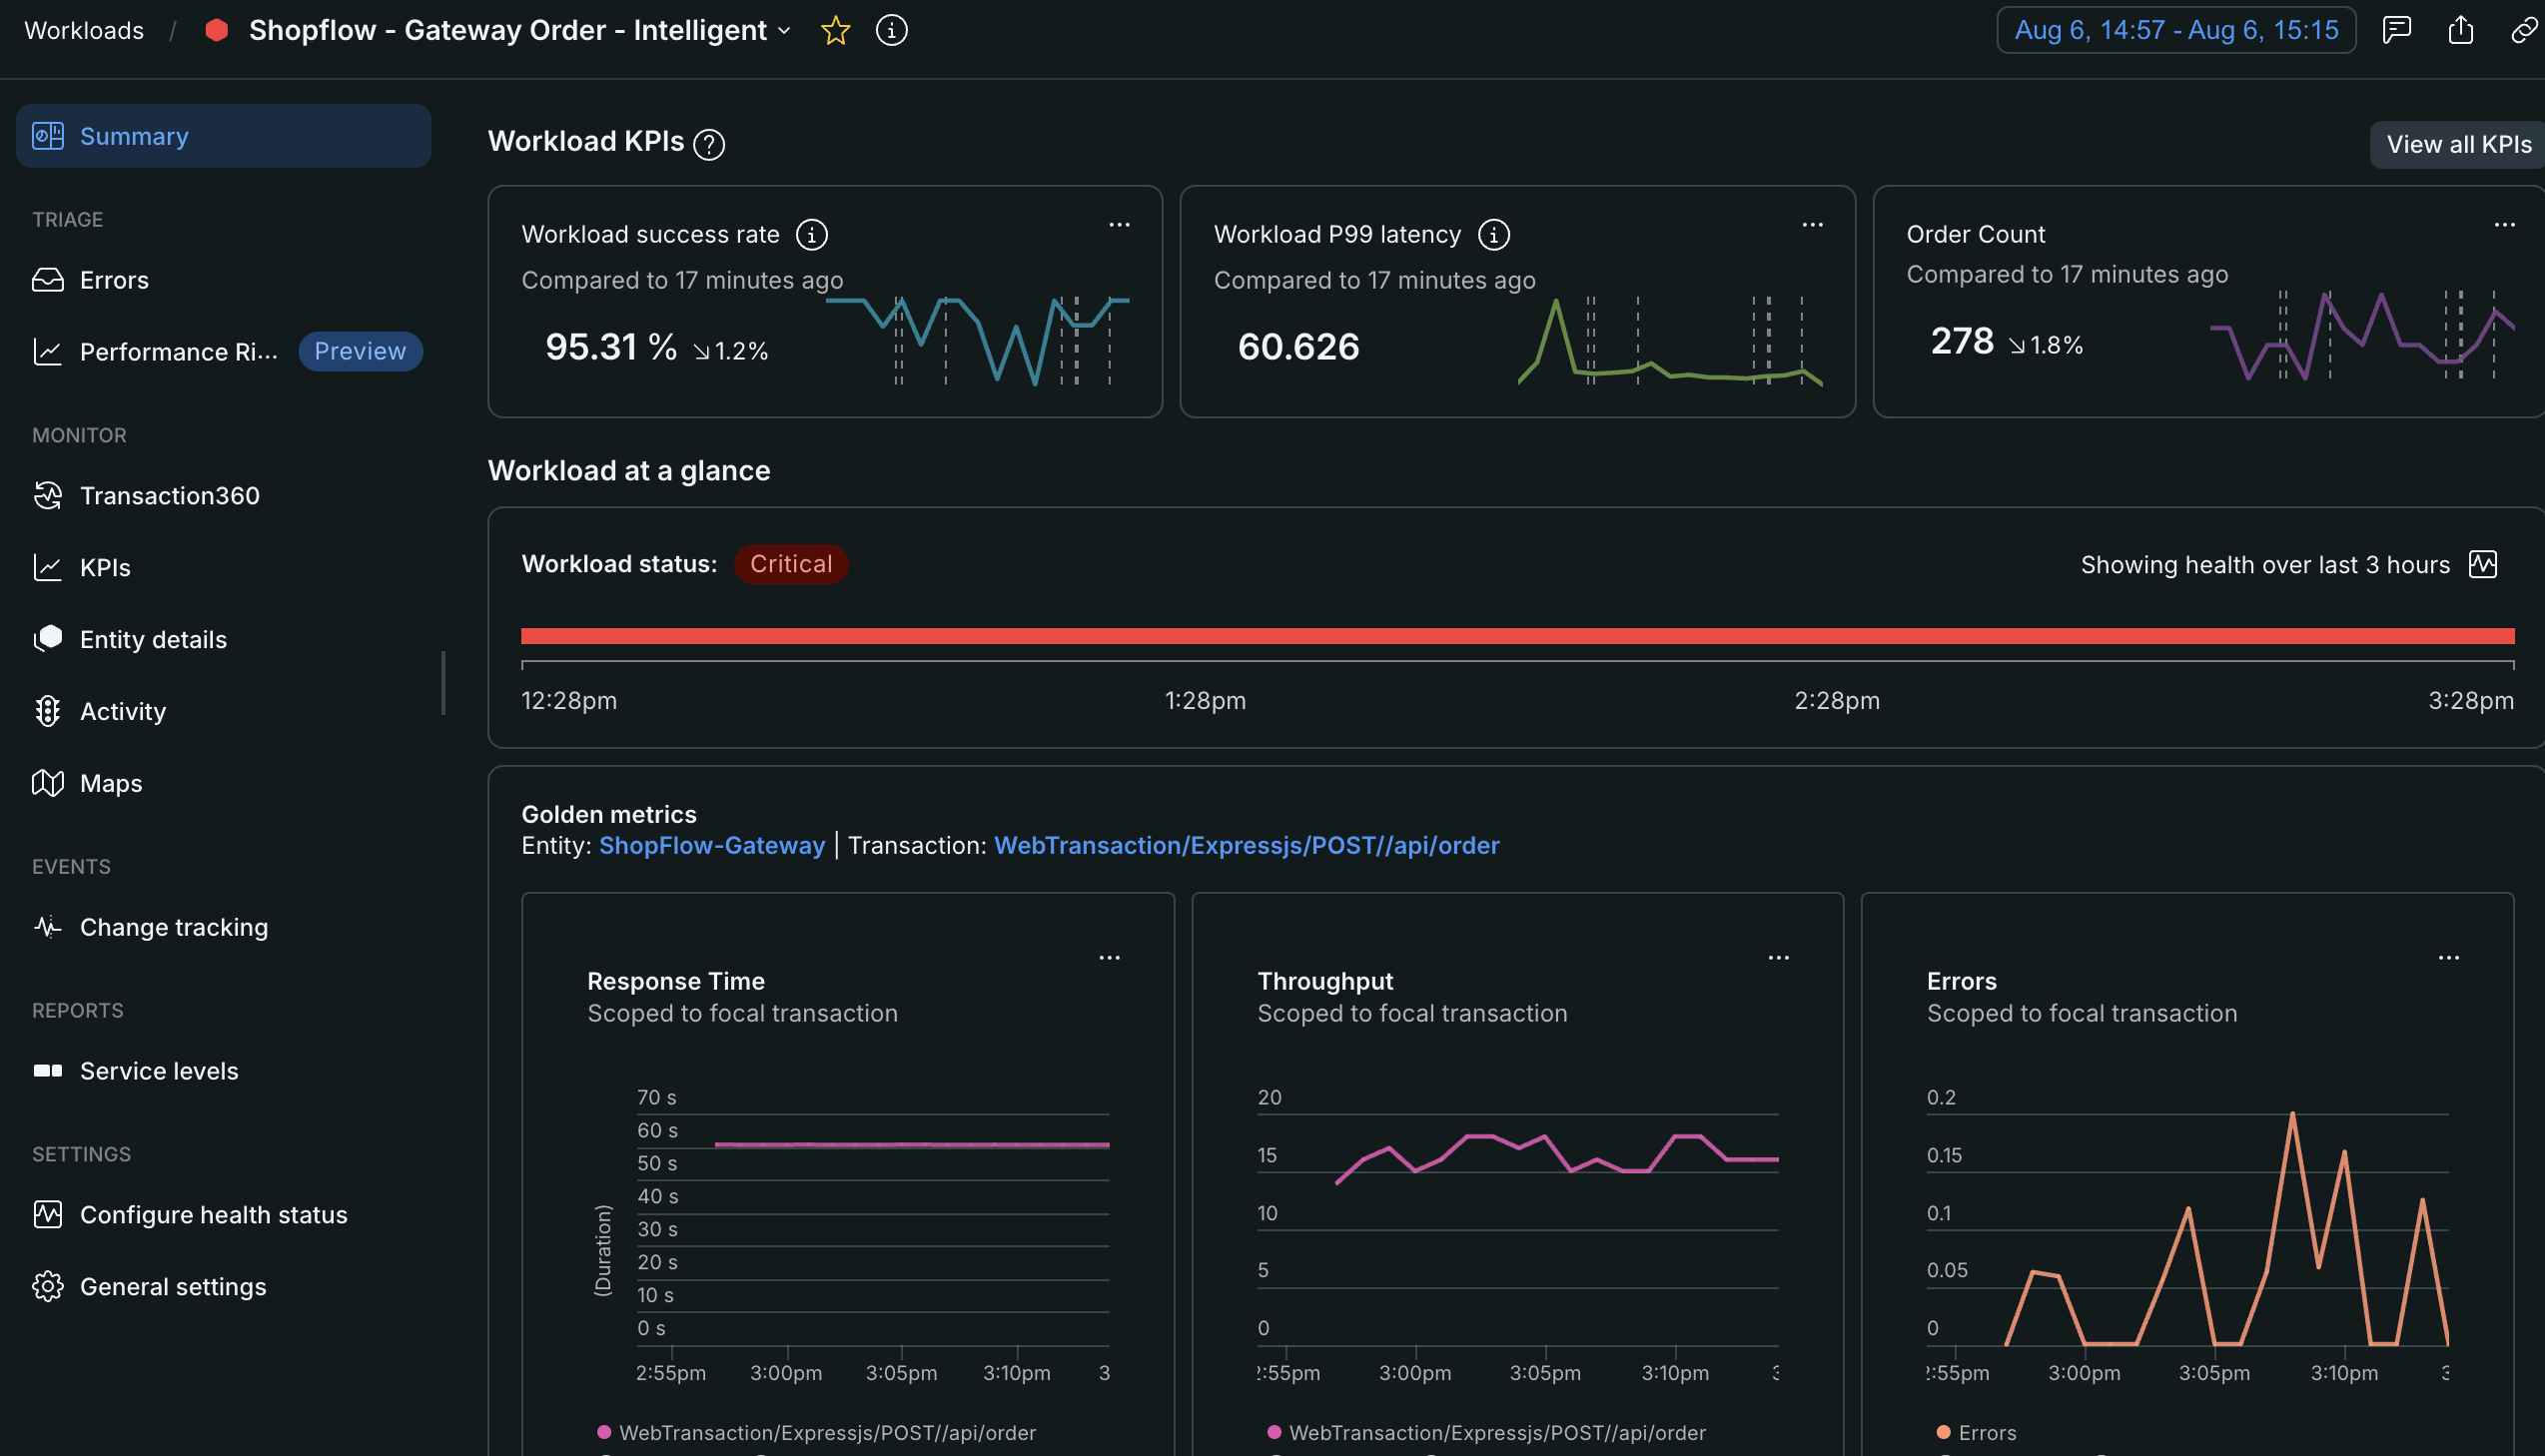
The Intelligent Workloads Summary page serves as your central operational cockpit, bringing full-stack dependencies, golden metrics, and custom business KPIs into a single unified view. This guide walks through using the Summary page components to monitor transaction health in real time and accelerate triage when performance degrades. As you scroll, the layout systematically guides your investigation from customer-facing impact straight to technical performance drivers.
The breakdown below uses a checkout transaction degradation as a recurring example to demonstrate how each view functions during an active incident.
Access Intelligent Workloads
After creating Intelligent Workloads, you can access them from the main Workloads page:
- Go to one.newrelic.com > All capabilities > Workloads.
- Use the Type filter to select Intelligent.
- Click a workload to open its dashboard.
AI Summary
Located at the top of the Summary page, the AI Summary automatically analyzes real-time performance data — including metrics, traces, and entity health — across all participating entities in your workload to accelerate incident response. Click Generate insights to instantly surface performance anomalies and get suggestions on where to begin your investigation. For instance, during a sudden checkout slowdown, the AI Summary can analyze your dependency chain and highlight high-latency database calls before you pull a single trace.
Requirements:
- New Relic AI must be opted-in for your account. Learn how to enable New Relic AI.
- For detailed requirements and troubleshooting, see AI insights for Intelligent Workloads.
Important
Pricing: AI insights generation incurs additional costs based on your New Relic AI usage. For more on New Relic AI pricing, see New Relic AI pricing documentation.
Workload KPIs
Positioned directly below the AI Summary, custom KPI tiles track key business indicators — such as order completion rates — directly alongside technical performance. Tracking KPIs allows your team to define system health by customer experience, alerting you the moment a business outcome is threatened. If your Checkout Success Rate KPI drops from 99% to 92%, you immediately know customer purchases are failing, rather than it being a benign background CPU spike.
You can display up to 3 KPIs on the Summary page at once. Two default KPIs are automatically added when you create an Intelligent Workload:
- Transaction Throughput: Tracks the total volume of incoming requests processing through your selected transaction over time.
- Transaction Error Rate: Monitors the percentage of failed transactions, giving you an immediate baseline of transaction reliability.
Learn more about managing KPIs →
Focal transaction golden metrics
Three side-by-side charts highlight Response Time, Throughput, and Errors scoped specifically to your focal transaction — the core transaction chosen when building your workload. Unlike standard APM views that mix all service traffic together, these golden metrics isolate the exact execution path of that central workflow. When your checkout KPI drops, reviewing these golden metrics helps you validate whether a simultaneous latency spike correlates with the business impact.
Participating entities
The bottom section breaks down performance across the top 20 services, databases, and serverless components actively processing your focal transaction. Scanning response time, throughput, and error rates across these dependencies helps you isolate precisely which microservice is failing. For example, sorting participating entities by response time during a checkout incident might reveal that a downstream payment-gateway database component accounts for 85% of total transaction latency, pointing you straight to the primary driver of degradation.
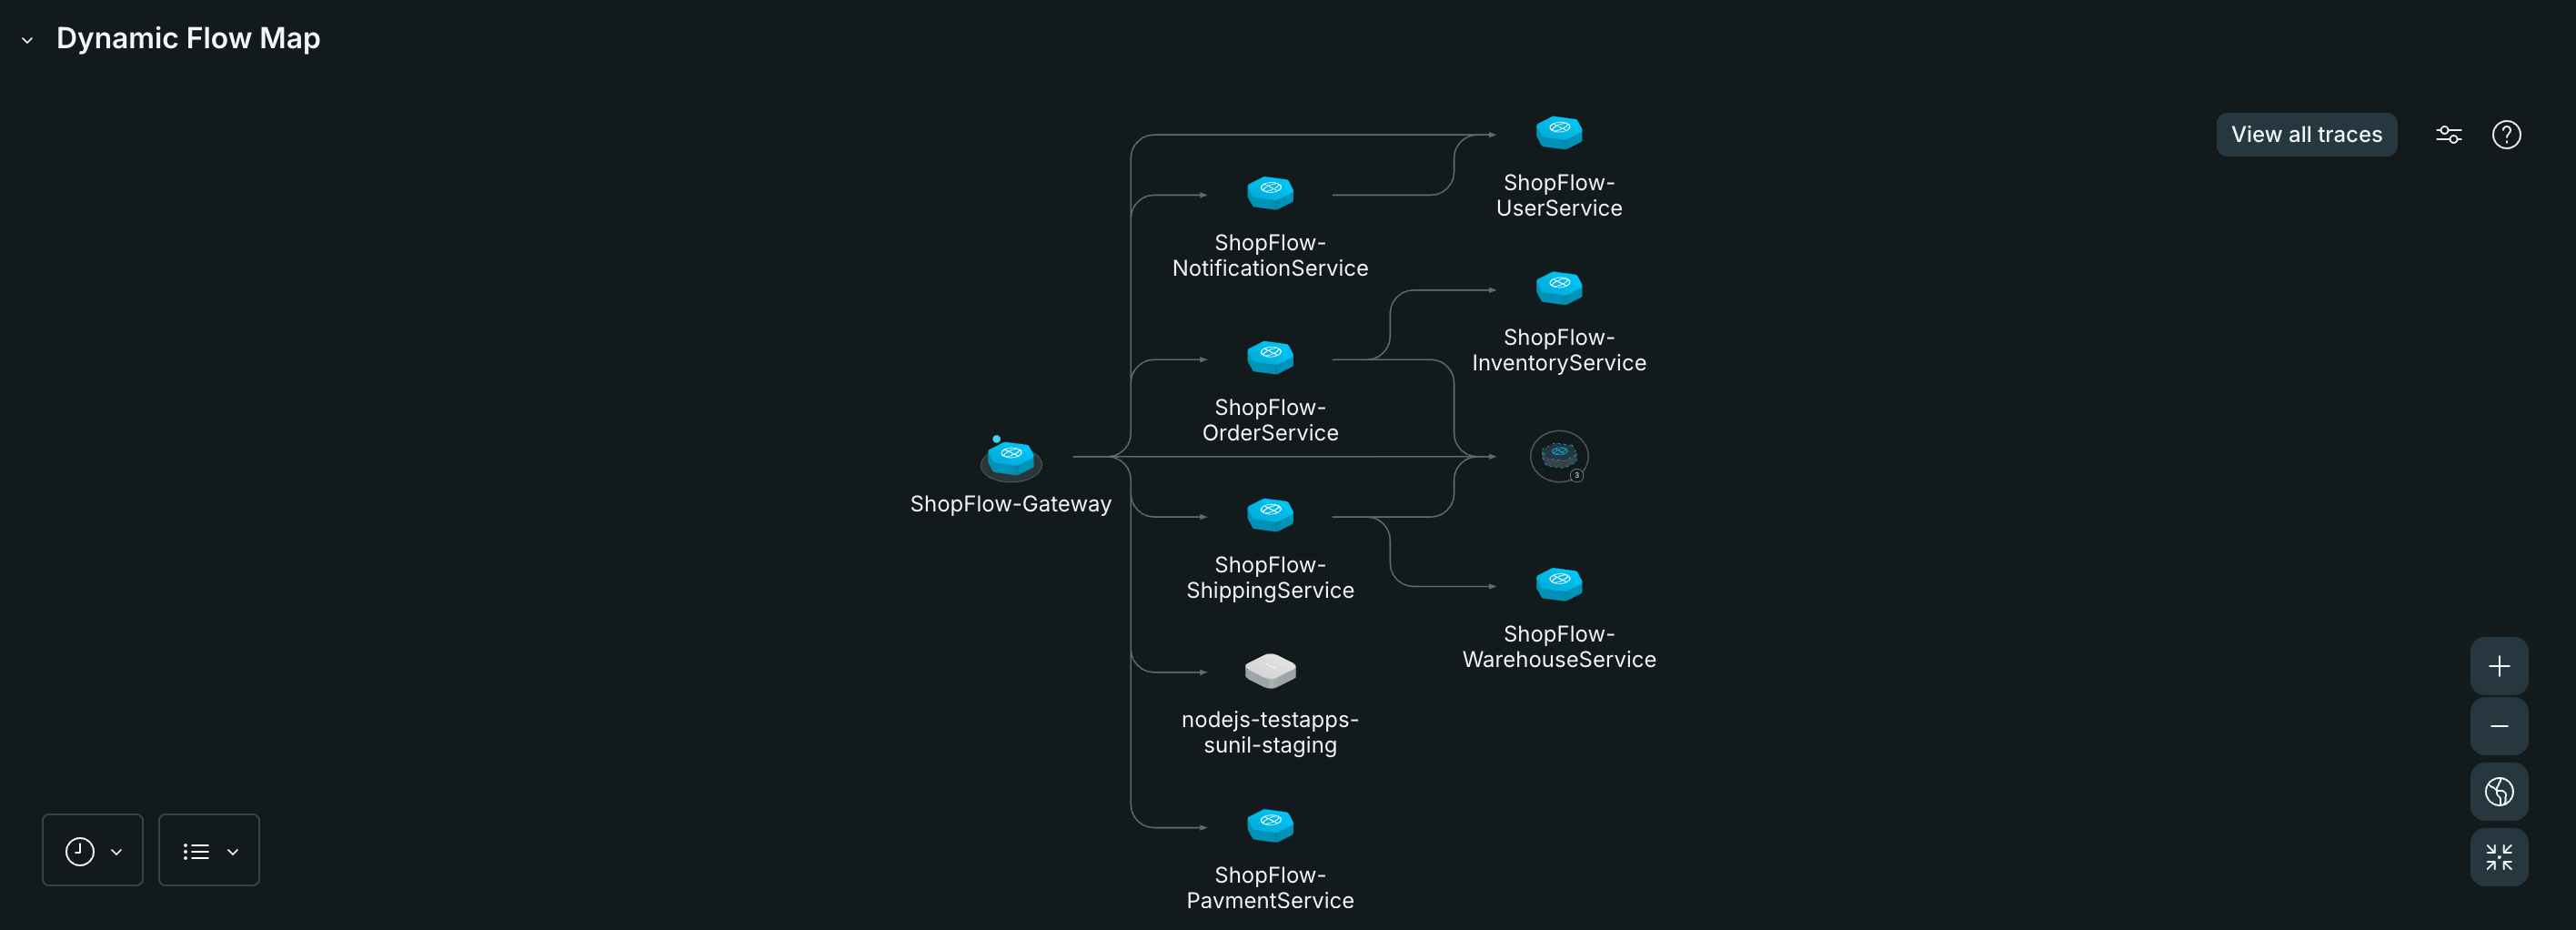
Dynamic Flow Map
The Dynamic Flow Map is a visualization tool that displays aggregated trace data to show how performance changes in upstream and downstream dependencies impact your focal service. By highlighting correlated anomalous latency and errors in traffic between services, the map helps you isolate performance bottlenecks across your transaction flow.
Understanding gaps in service maps
You may notice gaps or disconnected services in your service dependency visualizations. Here's what causes them and what you can do:
Common causes of gaps:
Low sampling rate: If trace sampling is too low for certain service connections, New Relic may not have enough trace data for that edge during your query window to display those relationships.
- What you can do: Check your agent's latest version and sampling configuration to take advantage of enhanced sampling capabilities.
Missing telemetry: A service in the middle of the trace may be participating in the trace correctly but failing to send span data to New Relic.
- What you can do:
- Verify the service is properly instrumented and configured to send data to New Relic
- Check network connectivity and firewall rules
- Review agent logs for errors
- When you can't fix it: Some service types or instrumentations (like certain AWS entity types) may not support sending span data. In these cases, gaps are expected and cannot be resolved.
- What you can do:
Disconnected services:
When a service in the middle of your trace fails to send data, you may see downstream services appear in your workload but disconnected from your focal entity. These disconnected services:
- Show up because they successfully send trace data to New Relic
- Appear isolated because their parent service is missing from the trace
- May have their own connected child services forming separate fragments
Tip
If you see persistent gaps or disconnected services, start by checking the sampling configuration and instrumentation health of the missing services. Focus on services that appear between your focal entity and the disconnected fragments.
Next steps
- Investigate with integrated experiences: Explore scoped sub-views including Errors Inbox, Transaction 360, and dependency maps
- Manage custom KPIs: Define business-specific metrics
- Configure health status: Customize how workload health is calculated
- Set up notifications: Get alerted on workload status changes